Linkschin Aggregator
A fast multi-media fetcher and aggregator. Built as a Turborepo monorepo with a Next.js frontend and a Python FastAPI backend for extracting direct download links.
Problem & solution scope
Linkschin is a high-throughput search and media aggregator designed to extract direct download links, split RAR game archives, and audio previews from complex Iranian media portals without routing media bandwidth through the server. Built as a unified Turborepo monorepo uniting a Next.js web application with an asynchronous Python FastAPI extraction engine.
System architecture
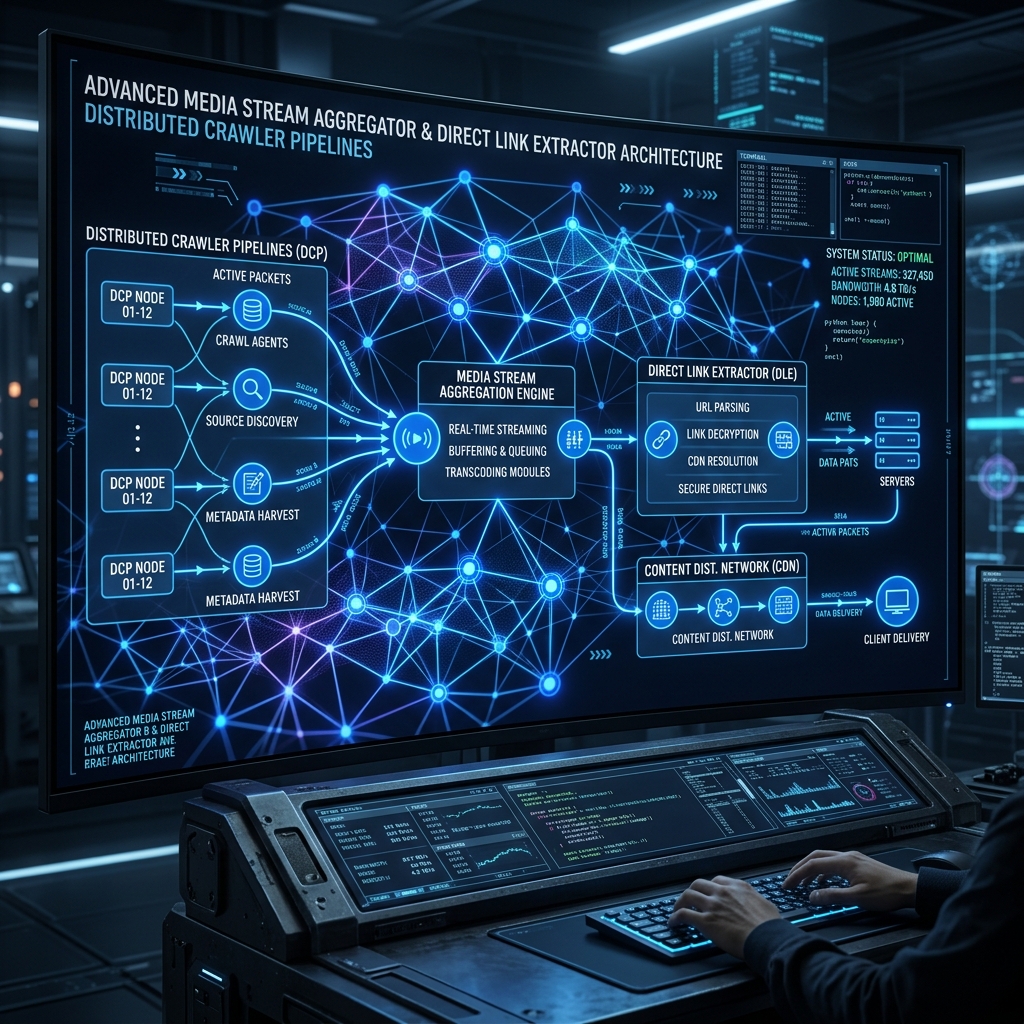
Decoupled Headless Extraction & Direct Streaming PipelineDesigned with strict separation between link discovery and media delivery. The backend handles distributed web scraping, anti-bot bypass, archive structure parsing, and link resolution, while direct file transfers stream strictly between the client and upstream CDNs, eliminating server bandwidth bottlenecks.
System Components
FastAPI Scraper Engine
Python 3.11+ / FastAPI / uv / PlaywrightExecutes distributed parsing of heterogeneous media sites with DOM caching, extraction fallback heuristics, and rate limiting.
Archive & Link Resolver
Regex & Multi-Part ParserDiscovers split game volumes (part1, part2, etc.), decodes obfuscated URLs, and extracts embedded archive passwords.
High-Performance Cache
Redis & SQLite Key-Value StoreCaches resolved download links and search queries with TTL invalidation to minimize upstream requests.
Next.js Web UI
Next.js 14 App Router / Tailwind CSSProvides fast, responsive search, media categorization (Movies, Games, Music), quality filtering, and one-click copy/download actions.
Data & Execution Flow
Search & Discovery
User queries media title from the Next.js frontend; request routes to the FastAPI aggregator.
Parallel Source Query
Engine dispatches concurrent asynchronous fetchers to upstream repositories with adaptive rate limiting.
Deep Link Extraction
Scraper extracts direct CDN links, split RAR parts, resolutions (1080p, 4K, x265), and archive passwords.
Direct Client Download
Normalized download manifests are returned to the user; file downloads stream directly from origin CDNs.
Engineered capabilities
Zero-Proxy Bandwidth Architecture: Server processes only lightweight JSON metadata while media downloads stream directly from CDNs.
Multi-Part Archive Intelligence: Automatically groups split game volumes and identifies required archive passwords.
Turborepo Polyglot Monorepo: Orchestrates Node.js/TypeScript frontend and Python backend tooling seamlessly.
Resilient Scraper Heuristics: Gracefully recovers from upstream HTML layout changes using fallback DOM selectors.
Audio Preview Streaming: Instant in-browser playback for music tracks without full album download requirements.
Engineering trade-offs
Zero-Proxy Media Delivery
Direct client-to-CDN link resolution prevents server network saturation and enables massive user concurrency on minimal server infrastructure.
uv & Poe Task Automation
Adopted uv for blazingly fast Python dependency resolution and poethepoet for unified cross-language monorepo task execution.
Monorepo Setup & Local Run
pnpm install

# Set up Python virtual environment
cd apps/api && python3 -m venv .venv
.venv/bin/python -m pip install -e ".[dev]"

# Run both frontend and backend concurrently
pnpm dev